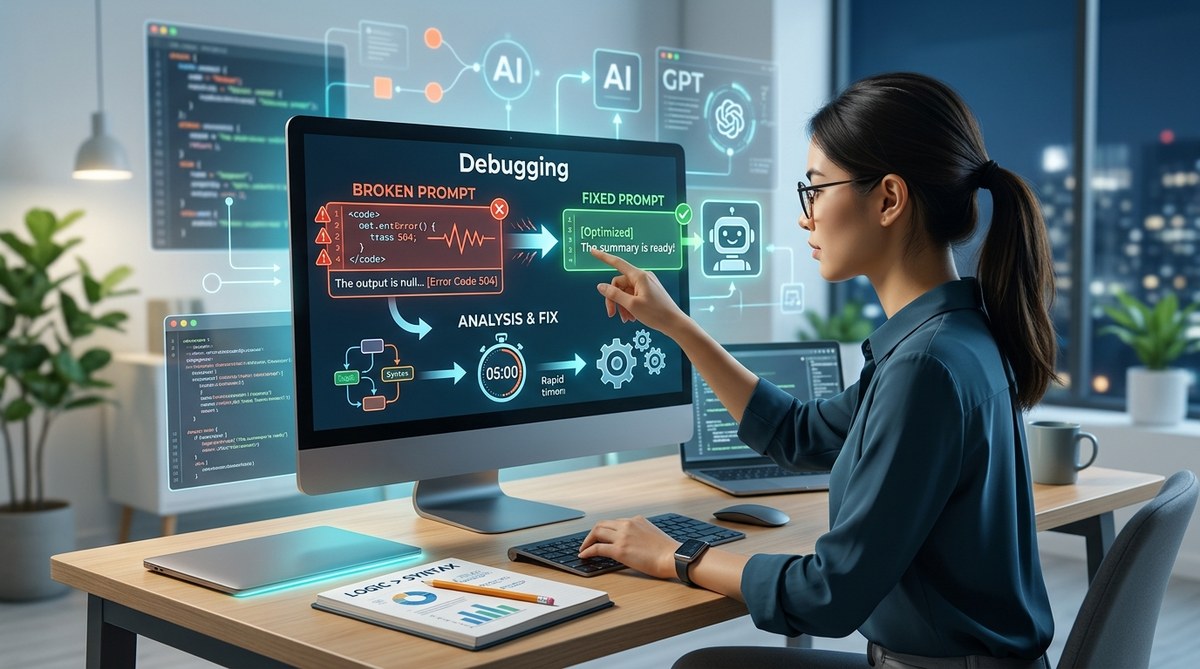
Your prompt was working fine an hour ago. Now the model is giving you gibberish, ignoring instructions, or hallucinating facts that were not in the training data. You change a few words, run it again, and get something even worse. This cycle of tweaking and testing can eat up your whole morning. But it does not have to. Debugging a broken prompt is a skill you can learn in a few minutes, and once you have a repeatable process, you will spend less time fighting your AI and more time building with it.
Most prompt failures come from one of five root causes: unclear instructions, missing context, format mismatches, model drift, or token limits. This guide gives you a five minute checklist to isolate the problem, apply a targeted fix, and verify the result so you can stop guessing and start shipping.
Why Prompts Break Without Warning
AI models are not deterministic in the way traditional software is. The same prompt can produce different outputs across sessions, model versions, or even temperature settings. When you are under pressure to deliver results, a broken prompt feels personal. It is not. The model is just doing what it was trained to do: predict the next most likely token. If your instructions are ambiguous or your context window is crowded, the prediction will wander.
Understanding the common failure modes helps you spot the issue faster. Here are the usual suspects:
- Instruction drift: The model follows the first part of your prompt but ignores the last.
- Format confusion: You asked for JSON but got a paragraph with code fences.
- Context overload: Too many examples or too much background noise push out the actual task.
- Model update side effects: A new model version changed how it interprets certain phrasing.
- Token clipping: Your prompt is longer than the context window, so the model drops the end.
The 5 Minute Debug Process
When a prompt breaks, your instinct might be to rewrite it from scratch. Resist that urge. A systematic approach saves time and teaches you what actually works. Follow these steps in order. Each step takes about one minute.
-
Isolate the variable. Change only one thing at a time. If you tweak the instructions and the examples at the same time, you will not know which fix worked. Start by reverting to your last known good version of the prompt. Run it again. If it still fails, the problem is not in your latest edits. It could be a model update or a change in your data pipeline.
-
Check the output format first. Many failures are not semantic. The model understands you, but it outputs markdown when you needed plain text, or it wraps the answer in a code block. If the format is wrong, the rest of your pipeline breaks. Add an explicit format instruction at the very end of the prompt: “Return only valid JSON with no markdown formatting.”
-
Test the instruction placement. Models pay more attention to the beginning and the end of a prompt. If your key instruction is buried in the middle, move it to the top or repeat it at the bottom. This simple shift often fixes refusal or omission errors.
-
Reduce the noise. Remove any examples, context, or system messages that are not strictly necessary for the current task. Each extra token is a chance for the model to get distracted. If the prompt works after you strip it down, add back the components one by one until you find the one that breaks it.
-
Run a control test. Use a trivial version of your prompt, like “Repeat the word apple.” If the model cannot handle that, the issue is not your prompt. It is the model endpoint, the API key, or the network. Fix that first before you keep debugging your wording.
Common Mistakes and How to Fix Them
Even experienced prompt engineers fall into the same traps. Below is a table of the most frequent errors and the targeted fix for each one.
| Mistake | Symptom | Fix |
|---|---|---|
| Vague persona | Output sounds generic or robotic | Give the model a specific role with a clear goal, like “You are a senior data analyst writing for a CTO.” |
| Missing constraints | Output is too long or too short | Add exact length limits: “Write no more than three sentences.” |
| Overloading with examples | Model copies the examples instead of following the instruction | Use fewer examples and put the instruction after them, not before. |
| Conflicting instructions | Model refuses to answer or gives contradictory info | Remove duplicate or contradictory statements. Keep one source of truth. |
| No output structure | Model returns a wall of text | Specify the structure: “Use bullet points. Start each point with a bold label.” |
Expert advice: “If your prompt worked yesterday and fails today, check the model version first. Providers update models silently all the time. A prompt that relied on a specific behavior can break overnight. Always pin your model version in production.” — Maester engineering team
When the Fix Is Not in the Prompt
Sometimes the problem is not your wording. It is the environment around the prompt. Here are three scenarios where you need to look outside the text.
Model drift happens more often than you think. A model that was fine-tuned in January may behave differently in June. If you are using a hosted API, check the changelog for the model you are calling. If you can, pin an older snapshot of the model until you have time to update your prompts.
Your context window is full. If your prompt includes a long document, multiple conversation turns, or a large set of few-shot examples, the model may truncate the end. Use a tool like Maester to measure your token count before you send the prompt. If you are close to the limit, trim the least important content.
The system prompt is overriding your user prompt. In many applications, a system prompt sets the overall behavior. If the system prompt says “Be concise” and your user prompt says “Write a detailed analysis,” the system prompt wins. Review your system prompt and make sure it aligns with the task.
Building a Prompt Testing Habit
Debugging a broken prompt is reactive. Preventing it from breaking in the first place is proactive. Start a small test suite for your critical prompts. Run it every time you make a change. You do not need a complex framework. A simple script that sends your prompt to the model and checks the output for expected keywords or format rules is enough.
For example, if your prompt always returns a list of three items, your test can check that the output contains three bullet points. If it fails, you know immediately. This habit catches regressions before they reach your users. If you want to go deeper, learn about prompt testing workflows that scale from prototyping to production to build a more robust system.
Another smart practice is versioning your prompts. When you save a prompt, save the model version, the temperature, and the date. This way, when a prompt breaks, you can compare it against the last known good configuration. A prompt versioning system can save you hours of guesswork.
Your Next Step When Nothing Works
You have run through the five minute checklist. You isolated the variable. You checked the format. You moved the instruction. You reduced the noise. You ran a control test. And the prompt is still broken. What now?
It is time to simplify the task itself. Can you break your prompt into two smaller prompts? Can you use a chain of thought approach where the model reasons step by step? Sometimes the problem is that you are asking the model to do too much in one go. Split the task into a pipeline. The first prompt extracts the key data. The second prompt formats it. The third prompt validates it. Each individual prompt is easier to debug.
If splitting does not help, consider that your use case may not fit the model you are using. A smaller model might lack the reasoning capacity for your task. A larger model might be overkill and introduce unnecessary randomness. Match the model to the complexity of the job. For more on this, see our guide on why prompt quality matters more than model size in 2026.
Start Debugging Smarter Today
You do not need to be a machine learning engineer to fix a broken prompt. You just need a process. The next time your AI gives you something unusable, stop yourself from rewriting the whole thing. Run the five minute checklist. Isolate the variable. Check the format. Move the instruction. Reduce the noise. Test the endpoint. Nine times out of ten, one of those steps will reveal the problem. The tenth time, you will know it is time to split the task or change the model.
Bookmark this page. Share it with your team. And the next time someone says “My prompt is broken,” you will have the answer ready.