Building an AI pipeline that hands work from a language model to a visual tool sounds straightforward on paper. You prompt the LLM, get output, and pass it along. In practice, it breaks in subtle ways that are genuinely hard to debug. The LLM produces text that is semantically correct but structurally useless for downstream image tools. Your evaluation suite gives everything a green light because it grades text, not pixels. And the whole thing collapses on edge cases you never thought to test. This guide covers how to think through each of these problems systematically.
Pipeline Reality Check
Multi-modal AI workflows fail most often at the handoff layer, where LLM text output meets visual tool input. Formatting LLM responses as structured, predictable payloads is the single biggest lever you have over reliability. Standard text-scoring evaluation frameworks are essentially blind to image quality, which means you need a separate testing approach for the visual leg of any pipeline you put into production.
The Gap Between Text Reasoning and Visual Execution
Most AI pipelines that include image steps share the same basic shape. An LLM handles the reasoning part: understanding user intent, making decisions, generating instructions. A downstream visual tool takes those instructions and operates on pixels. The two components are good at very different things, and that difference creates friction at the boundary between them.
Language models are probabilistic. They produce output that is contextually plausible, which is wonderful for conversation and reasoning, but dangerous when a visual tool expects a precise, deterministic input format. If your image processing step expects a JSON object with specific fields and the LLM decides to wrap its output in a friendly explanation, the pipeline breaks immediately.
This is not a model quality problem. It is a prompt design problem. And it is fixable.
To get a concrete sense of what these visual tools actually do once they receive instructions, spending time with a capable AI photo editor grounds your mental model before you start designing handoff formats. Understanding the kinds of operations these tools expose gives you a better instinct for what your LLM outputs need to specify precisely versus what can stay flexible.
Structuring LLM Outputs as Reliable Handoff Payloads
The most effective pattern for multi-modal pipelines is treating the LLM output as a formal interface contract rather than free-form text. This means designing your prompts to produce structured, typed, predictable output every single time.
What a Good Handoff Payload Looks Like
A reliable handoff payload from the LLM to a visual tool has a few non-negotiable properties. Every one of these is something you can enforce through prompt design and validated with a schema check before anything reaches the image layer.
- Fixed schema. The output always contains the same keys in the same structure. Missing optional fields should be explicitly null, not absent entirely.
- Typed values. Color values are always hex strings. Dimensions are always integers. Operations come from a controlled vocabulary, not free-form descriptions that a visual tool has to interpret.
- No prose leakage. The payload contains zero explanatory text. Rationale and caveats belong in a separate reasoning field or are stripped entirely before the payload moves downstream.
- Explicit defaults. If a visual parameter is unspecified by the user, the payload includes the default value explicitly rather than omitting the field and hoping the downstream tool guesses correctly.
- Structured error signals. When the LLM cannot confidently produce a valid payload, it returns a structured error object rather than a best-guess output that will silently produce wrong image results.
The prompt engineering work here is mostly about constraint and formatting instructions. System prompts should specify the exact output schema with a JSON example. Few-shot examples should all conform to the schema, including edge cases. Including a negative example showing what a broken output looks like, and explicitly telling the model not to produce it, is worth the extra tokens.
Output Format Comparison for Visual Tool Integration
Developers often debate whether JSON, XML, or structured natural language is the right output format for LLM-to-tool handoffs. Performance varies significantly across the dimensions that matter for image pipelines specifically.
LLM Output Formats Compared on Key Pipeline Criteria
| Format | Schema Enforcement | Parse Reliability | Best Fit |
|---|---|---|---|
| JSON with native function calling | High | Very high | Production pipelines with stable schemas |
| JSON via prompt-only instruction | Medium | Medium to high | Prototyping, simpler schemas |
| XML | Medium | Medium | Hierarchical data with mixed content types |
| Structured natural language | Low | Low | Human review steps only, never tool inputs |
For image pipelines specifically, JSON with the model’s native structured output mode is the clear choice for production. It eliminates an entire class of parsing failures that plague prompt-only approaches at any meaningful scale.
Where Standard Evaluation Frameworks Stop Working
Prompt evaluation for text-only systems is already hard. You are measuring subjective quality with automated metrics that are proxies at best. For multi-modal pipelines, the problem compounds because the actual outcome you care about is an image, and text-scoring rubrics have nothing to say about that.
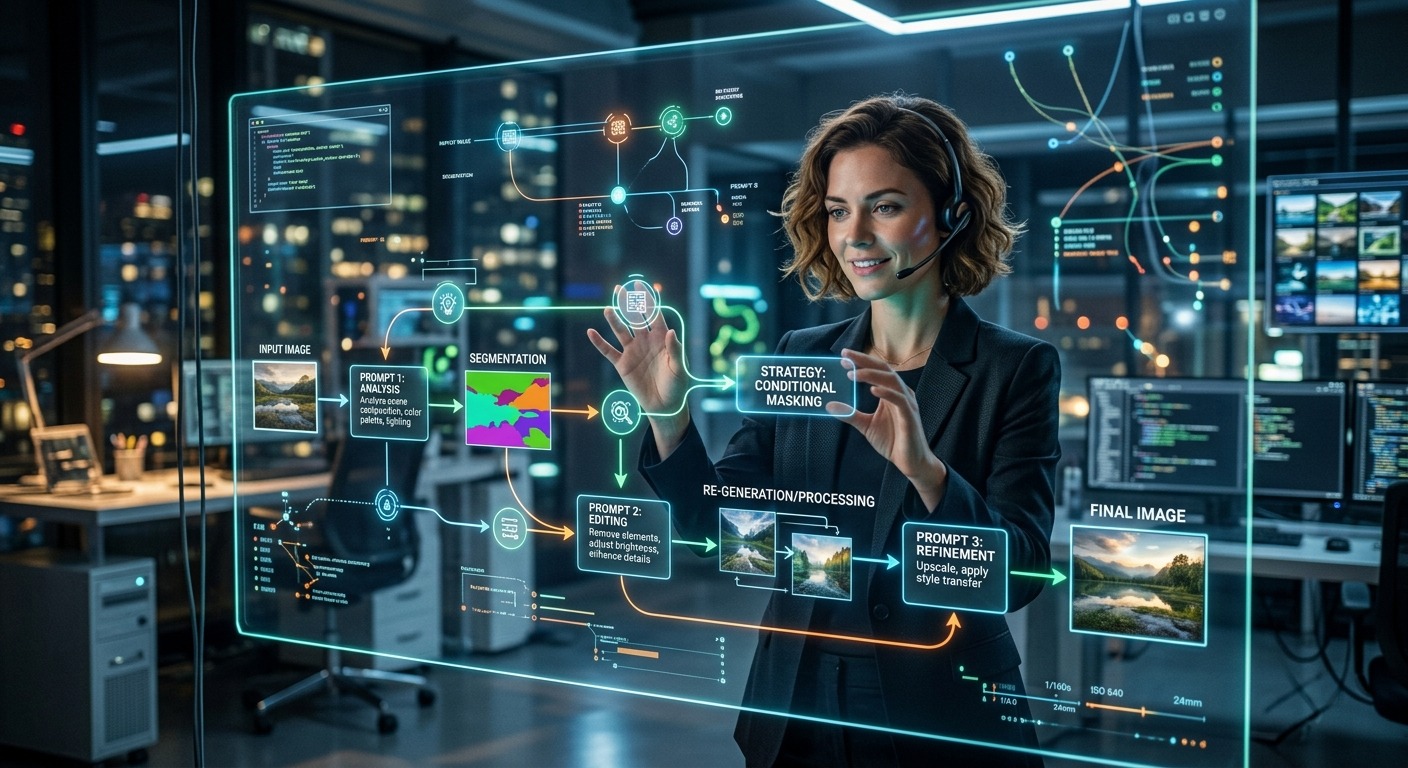
Consider a pipeline where the LLM generates image editing instructions. A text evaluator can confirm the output is valid JSON, that all required fields are present, and that the values are within expected ranges. What it cannot tell you is whether the resulting image looks right, whether a subtle hue shift produced the intended mood, or whether a crop operation cut off the wrong part of the subject.
NIST’s AI evaluation guidance consistently emphasizes that metrics should be tightly coupled to the actual outcomes that matter for the system in question. For image pipelines, that means you need at minimum two separate evaluation layers: one for the LLM handoff payload and one for the visual output itself.
The text layer evaluates structural correctness: schema validity, value ranges, completeness, and type conformance. The visual layer requires either human review or automated image quality metrics, depending on your scale and latency budget. Neither layer substitutes for the other. Passing one while failing the other means your pipeline is broken.
Practical Testing Approaches for the Visual Leg of Your Pipeline
Testing image outputs requires a different mindset than testing text. You are not grading an answer against a rubric. You are checking whether a transformation produced an acceptable result within a defined range of acceptable results, and that range is often context-dependent.
- Golden image comparison. For deterministic operations, maintain a reference output library. Compare pixel histograms or perceptual hash signatures rather than exact pixel matches, since rendering engines introduce minor variation across runs.
- Boundary condition testing. Test the extremes of each numeric parameter the LLM controls. The middle of the value range almost always works. The edges reveal where the visual tool breaks or produces unexpected output.
- LLM-as-judge for visual outputs. For non-deterministic results, pass the output image to a multimodal LLM and ask it to score the result against specific criteria. This scales better than pure human review but requires careful calibration of the judge prompt itself.
- Regression testing on payload changes. When you update the LLM prompt, run a fixed test set and compare the resulting payloads. A payload diff that looks minor on paper can produce a significant visual difference downstream.
- Latency-segmented review cadence. Separate fast automated checks from slower human-review passes. Gate on automated checks in CI and schedule human review on a sampling cadence tied to release cycles, not per-commit.
Orchestration Patterns That Survive Production Load
Beyond prompt formatting and evaluation, the structural design of the pipeline affects reliability in ways that are easy to overlook during early prototyping.
The most robust pattern is a validation middleware layer positioned between the LLM and the visual tool. The LLM produces output, the middleware validates it against the expected schema and value constraints, and only a confirmed-valid payload reaches the image processing step. Failed validation returns to the LLM with a targeted correction prompt rather than passing bad data downstream.
This pattern adds latency on failure cases but dramatically reduces the rate of corrupt image outputs and gives you a clean audit trail. Every bad payload is logged with the prompt that produced it, which makes systematic prompt improvement much faster than debugging after the fact.
Conditional branching is the other pattern worth building in early. Not every user request requires the same image processing steps. An LLM that classifies the request before generating the full payload reduces the instruction surface area, which in turn reduces the rate of hallucinated parameter values. A classification step with a narrow output space is much more reliable than a single prompt that must reason about all possible execution paths simultaneously.
Building Confidence Across the Full Modality Boundary
The central challenge of multi-modal AI pipelines is that reliability requires discipline at every boundary. The LLM prompt controls the quality of the handoff. The handoff format controls the reliability of the visual tool. The evaluation strategy controls how quickly you catch problems that slip through both.
Teams that get this right treat the LLM output not as the end of a prompt engineering problem, but as the beginning of an interface design problem. They write prompts the same way they write API contracts: with explicit schemas, typed fields, and failure modes accounted for in advance rather than discovered in production.
The payoff is a pipeline that degrades gracefully instead of silently. When something breaks, you know which layer broke, you have the logs to diagnose why, and you have the test coverage to confirm your fix worked before it reaches users. That is the standard worth building toward, and it is fully achievable with the right prompt design decisions made from the start.