Feeding an image to a model and expecting useful output is not one prompt engineering problem. It is three problems stacked on top of each other: you need the model to see accurately, reason correctly, and respond in a format your downstream system can actually use. Most practitioners nail one of those, struggle with the second, and forget the third entirely until something breaks in production.
Vision-language models need more than an image and a question. They need structured prompts that constrain output, assign roles, and chain reasoning steps explicitly.
- Constrained output formatting using JSON schemas dramatically reduces hallucination in image extraction tasks.
- Role-scoped system prompts focus a VLM’s attention on specific visual domains, improving accuracy and consistency across runs.
- Anchored chain-of-thought instructions paired with image inputs produce verifiable, auditable reasoning rather than opaque answers.
Why Vision-Language Models Require a Different Prompting Mindset
Text-only LLMs have one input modality. You can inspect the prompt, trace the tokens, and reason about what the model sees. With VLMs, the image encodes information that never appears in your text prompt. The model must bridge both channels simultaneously, and that bridging process is where most prompt failures happen.
A VLM processing a photograph of a handwritten equation is doing substantial implicit work: detecting the image region, parsing handwriting into symbols, mapping those symbols to mathematical concepts, and then reasoning about them. If your prompt does not guide that pipeline, the model improvises. Sometimes it improvises well. Often it does not.
The good news is that VLMs respond well to prompt structure. They behave more like a trained analyst than a general-purpose chat assistant when you give them explicit instructions about what to look for, how to format the response, and what reasoning steps to follow. The patterns below are designed to take advantage of exactly that.
Constrained Output Formatting for Image Extraction Tasks
The fastest way to improve VLM reliability is to stop asking for prose and start asking for structure. When a model knows it must return a JSON object with specific fields, it stops filling gaps with plausible-sounding text. The constraint forces precision.
Defining Output Schemas in the System Prompt
The most effective approach is to define your output schema directly in the system prompt, before the image or user query appears. Something like this works well in practice:
You are a document extraction agent. Always respond with valid JSON matching this schema:
{
  "document_type": string,
  "fields_extracted": [
    { "label": string, "value": string, "confidence": "high" | "medium" | "low" }
  ],
  "notes": string | null
}
Do not include any text outside the JSON object.
This single change cuts hallucination rates noticeably in document parsing tasks. The model still has to see and interpret the image, but its output is funneled into a structure you control. Your parsing logic never has to handle free-form text.
A few practices worth building into your output schema design:
- Use an enum for categorical fields like confidence level or document type to prevent invented values
- Include a
notesorfallbackfield so the model can signal uncertainty rather than guess silently - Request a raw string version of extracted text before any interpreted or normalized value
- Version your schema inside the prompt so logs stay interpretable as schemas evolve over time
Role-Scoped System Prompts and the Attention Effect
VLMs respond to role framing in the system prompt, just as text models do. But with images in the loop, role framing does something additional: it narrows the model’s attention to the parts of an image that are relevant to the assigned role.
A system prompt that says “You are a radiology report assistant. Focus only on visible anomalies in the image and report their location, size, and confidence level” will produce fundamentally different behavior than a generic “Describe this image” instruction, even when both receive the same input photograph.
The mechanism is not mysterious. The model has been trained on enough role-specific visual content that a well-framed role activates the right internal representations. You are not tricking the model. You are aligning its priors with your use case.
Role scoping works best when you follow these steps in order:
- Name the role explicitly and make it domain-specific, not just “assistant” but “invoice parsing specialist” or “floor plan analysis agent”
- State what the role does not look at, not just what it focuses on, to prevent attention drift toward irrelevant image regions
- Pair the role with a concrete output task so the model understands what success looks like for this specific call
- Include a brief description of the expected image type in the system prompt rather than the user turn, priming the model for variable scan quality or oblique camera angles before they appear
That fourth step is the most underused. Telling the model in advance what kinds of images it will see prepares it to handle those conditions rather than being surprised by them mid-inference.
Chain-of-Thought Instructions for Complex Visual Inference
Chain-of-thought prompting is well established in text contexts. A chain-of-thought study by Wei et al. demonstrated that asking models to show intermediate reasoning steps significantly improves performance on complex tasks. The same effect holds for VLMs, with one important adjustment: you need to anchor the reasoning steps to visible image evidence.
A prompt like “Reason step by step” is too vague when an image is involved. The model may reason about the image, or it may reason about the question and use the image only loosely. Anchored chain-of-thought looks different:
Step 1: Identify and quote the specific text or values visible in the image.
Step 2: State what those values represent in context.
Step 3: Perform any required calculation or inference.
Step 4: Return your final answer with the step number that justifies it.
This pattern forces the model to ground its output in what it literally observed, rather than making inferences that skip visual evidence. It also makes errors traceable. If Step 1 contains a misread, you catch it before it compounds through Steps 2 and 3. That auditability matters a great deal in regulated or high-stakes applications.
Visual Reasoning Pipelines in Production Settings
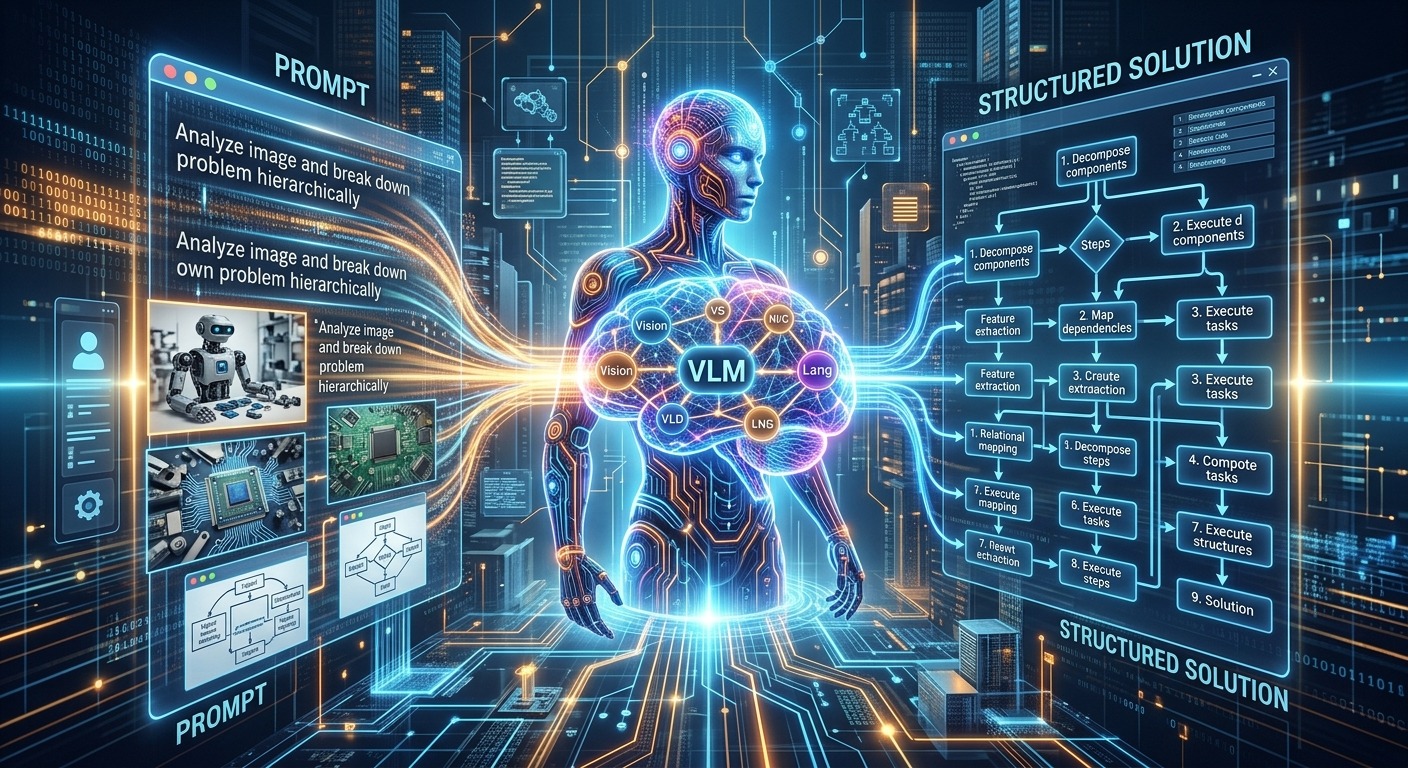
These patterns are useful in isolation, but they become powerful when chained. A production visual reasoning pipeline typically looks like a sequence of scoped agents, each with a constrained output, passing structured results forward to the next stage.
Consider how this plays out for a math tutoring application. A student submits a photo of a handwritten problem. The first VLM call extracts and normalizes the equation into structured text. A second call, now working with the clean equation as text input, applies chain-of-thought reasoning to produce a step-by-step solution. A third call validates the steps for logical consistency before the result reaches the student.
This is exactly the kind of architecture behind production tools that implement a photo math solver workflow: image input triggers a chain of structured inference steps, each building on verified output from the one before it, rather than asking a single model call to do everything at once. The result is auditable and not just correct.
Chaining also lets you assign different models to different stages. A cheaper, faster model handles initial extraction where errors are easy to catch. A more capable model handles the reasoning step where subtlety matters. You get better results at lower cost than if you routed everything to the most expensive model available.
Comparing Prompt Strategies Across Leading VLMs
No single prompt pattern works identically across models. GPT-4o, Claude, and Gemini each have different training emphases and system-prompt behaviors. The table below reflects patterns observed across practical deployment scenarios, not marketing claims from any vendor.
Prompt Strategy Behavior Across Three Leading Vision-Language Models
| Prompt Strategy | GPT-4o | Claude (Sonnet tier) | Gemini 1.5 Pro |
|---|---|---|---|
| JSON schema in system prompt | Strong adherence; rarely breaks schema on ambiguous inputs | Very strong; may add a reasoning field unless schema explicitly forbids it | Good; may wrap JSON in markdown code fences by default |
| Role-scoped system prompt | Responds well; role precision improves accuracy on niche visual domains | Excellent system-prompt adherence; role constraints hold across long sessions | Moderate; role drift can appear in multi-turn contexts |
| Anchored chain-of-thought | Strong; explicit step structure is followed; image grounding is reliable | Strong; naturally verbose in step outputs, which aids auditability | Strong on clear images; degrades faster on low-resolution or noisy inputs |
| Chained multi-call pipeline | Excels at the image-to-structured-text extraction stage | Best choice for reasoning-heavy middle stages requiring auditability | Competitive for high-resolution image analysis at scale |
| Best deployment fit | Document extraction, receipt parsing, form digitization | Step-by-step reasoning, educational applications, compliance review | Large-scale image batch processing, multi-image context windows |
Treat this table as a starting point, not a verdict. Your specific image types, latency requirements, and volume will shift these rankings. Running a focused benchmark with your own representative data before committing to a model is always worth the time investment.
Turning Patterns into a Repeatable Engineering Decision
The goal of all these patterns is not to find the perfect prompt. It is to build a system where failures are visible, fixable, and contained at the right stage. Structured outputs make failures visible. Role-scoped prompts make them less frequent. Chained reasoning makes them fixable before they propagate downstream.
When you are deciding which patterns to apply, start with the output your downstream system actually needs. If it needs JSON, begin with output schema constraints before anything else. If it needs explainable answers, anchored chain-of-thought is your first investment. If reliability across many image types matters more than perfection on any single image, pipeline chaining with model specialization per stage is the right architecture.
The benchmark comparison above points to a practical principle: no single model dominates every dimension. GPT-4o tends to excel at extraction. Claude tends to excel at structured reasoning. Gemini scales well with image volume. A real production pipeline often reaches for more than one, routing tasks by their dominant challenge rather than committing all traffic to one provider.
The reusable decision rule is this: match the prompt pattern to the failure mode you are trying to prevent. Hallucinated values? Constrain the output. Domain confusion? Scope the role. Reasoning errors that compound across steps? Chain and verify at each stage independently.
None of these patterns require exotic tooling or proprietary infrastructure. They require deliberate prompt construction, a test set of representative images, and the discipline to evaluate outputs rather than assume them. That combination outperforms any single clever prompt, every time.