You are staring at a production prompt that just generated a hallucinated customer support response. The tone was wrong, the facts were made up, and the output made your team look unprofessional. This happens more often than most teams admit. The root cause is rarely the model itself. It is almost always a gap in your prompt testing framework.
Most teams treat prompt engineering like a creative writing exercise. They tweak words, cross their fingers, and deploy. That approach is dangerous in 2026. Models change. Edge cases multiply. A prompt that worked last week can fail today. The fix is a systematic prompt testing framework that catches errors before they reach users. This guide shows you exactly how to build one.
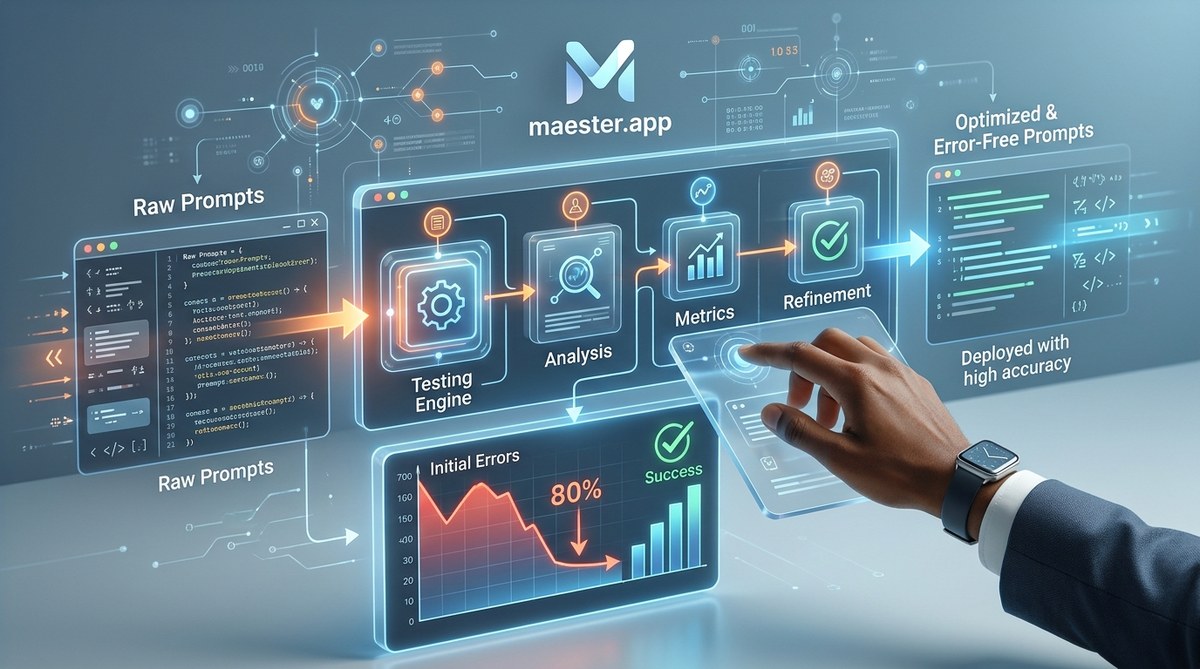
A prompt testing framework is a repeatable system for validating prompts against real-world inputs before deployment. It includes test cases, automated evaluations, version control, and error tracking. Teams that adopt this approach report an 80% reduction in prompt-related errors. This article walks through the five components you need, the common mistakes to avoid, and a step-by-step plan to implement it today.
Why Most Prompt Testing Fails
The biggest mistake teams make is testing prompts in isolation. They run one example, see a good result, and ship it. That is like testing a car engine by turning it on once in the driveway. You miss the potholes.
Here is what happens when you skip structured testing:
- Model drift catches you off guard. A model update changes how your prompt behaves. You only notice when users complain.
- Edge cases go unhandled. Your prompt works for 90% of inputs. The other 10% produce nonsense or harmful content.
- Regressions sneak in. You fix one problem, break something else, and nobody catches it.
- Team collaboration breaks down. Different engineers make changes without visibility. Prompts become a black box.
A prompt testing framework solves all of these. It turns prompt development from guesswork into engineering.
The Five Components of a Prompt Testing Framework
Building a framework does not require a massive budget or a dedicated platform. You can start with a spreadsheet and a Python script. The structure matters more than the tools.
1. A Test Case Repository
This is your source of truth. It contains every input your prompt should handle, along with the expected output. Think of it like unit tests for your prompts.
- Include happy path examples (the standard cases).
- Include edge cases (empty inputs, very long inputs, unusual formats).
- Include adversarial examples (inputs designed to confuse the model).
- Include failure cases (inputs where the model should refuse or ask for clarification).
Aim for at least 50 test cases per prompt. More is better.
2. An Automated Evaluation Harness
You need a way to run all test cases against your prompt and score the results. This can be as simple as a script that sends each input to the API and compares the output to your expected result.
- Use exact match for simple outputs.
- Use semantic similarity for open-ended outputs.
- Use a secondary LLM as a judge for complex criteria like tone or safety.
3. Version Control for Prompts
Your prompts should live in a version control system alongside your code. Every change gets a commit. Every commit includes the test results.
- Store prompts as plain text files.
- Name them with a version number or date.
- Keep a changelog that explains why each change was made.
4. A Regression Suite
This is a subset of your test cases that runs every time you change a prompt. It catches regressions before they reach production.
- Run the full suite on every commit.
- Run the regression suite on every deployment.
- Flag any test that passes in staging but fails in production.
5. An Error Logging and Alerting System
When a prompt fails in production, you need to know immediately. Log every generation, including the input, output, latency, and any errors.
- Set up alerts for sudden drops in quality metrics.
- Log all user feedback on outputs.
- Review logs weekly to identify new edge cases.
Common Mistakes and How to Fix Them
Even with a framework, teams make predictable mistakes. Here is what to watch for.
| Mistake | Why It Happens | The Fix |
|---|---|---|
| Testing only with perfect inputs | Easy to write, unrealistic | Add edge cases from production logs |
| Using the same model for testing and production | Model versions differ | Test with the exact model version you deploy |
| Ignoring latency and cost | Focus only on quality | Add latency and token count to your test results |
| Not updating test cases | Test cases go stale | Review and add new cases monthly |
| Manual evaluation only | Slow and inconsistent | Automate at least 80% of evaluations |
A Step-by-Step Plan to Build Your Framework
You can implement this in a week. Here is the sequence.
- Audit your existing prompts. List every prompt you use in production. Note which ones have caused errors.
- Write your first 50 test cases. Start with the most error-prone prompt. Include 10 happy paths, 20 edge cases, 10 adversarial inputs, and 10 failure cases.
- Build a simple evaluation script. Use Python and your LLM provider’s SDK. Run all 50 test cases and save the results to a file.
- Set up version control. Move your prompts into a Git repository. Commit the current version along with the test results.
- Create a regression suite. Pick the 10 most important test cases. Run them every time you edit the prompt.
- Add logging to production. Capture every generation and store it in a database for later analysis.
- Review and iterate. After one week, review the results. Add new test cases based on what you learned.
“The teams that cut errors the fastest are the ones that treat prompt testing like software testing. They write test cases first, then build the prompt. They run tests on every change. They log every failure. It is not glamorous, but it works.” – Engineering lead at a major AI platform
The Metrics That Matter
A prompt testing framework is only useful if you measure the right things. Track these metrics from day one.
- Error rate. Percentage of generations that fail your quality checks.
- Test coverage. Percentage of known edge cases covered by your test suite.
- Regression rate. Number of previously passing tests that fail after a change.
- Time to detect. How long between a bad deployment and the first alert.
- Time to fix. How long between detection and a working fix.
Set a baseline for each metric. Then track improvement weekly.
Building the Habit
The hardest part of a prompt testing framework is not the setup. It is the discipline to use it. Here is how to make it stick.
- Make testing part of your definition of done. No prompt ships without passing the regression suite.
- Automate the boring parts. Set up CI/CD to run tests on every pull request.
- Celebrate catches. When the framework catches a bad prompt before deployment, share it with the team. That builds buy-in.
- Keep the test cases visible. Put the top failing test cases on a dashboard. Make them impossible to ignore.
For more on how to structure your prompts for testability, check out our guide to mastering prompt engineering. If you are dealing with complex multi-step workflows, prompt testing workflows that scale from prototyping to production will help you adapt this framework.
Your First Week Action Plan
You do not need to build everything at once. Here is a realistic first week.
Day 1: Audit your prompts. Pick the one that causes the most errors.
Day 2: Write 20 test cases for that prompt. Include the last three failures you saw in production.
Day 3: Build a script that runs those 20 test cases and prints pass/fail.
Day 4: Set up a Git repository for your prompts. Commit your test cases and your script.
Day 5: Run the full suite. Fix any failures. Commit again.
Day 6: Add logging to production for that prompt.
Day 7: Review the data. Write five more test cases based on what you learned.
By the end of the week, you will have a working prompt testing framework for your most important prompt. Next week, do it again for the second most important one.
Turning Testing Into a Superpower
A prompt testing framework does more than cut errors. It changes how your team thinks about prompts. Instead of hoping for the best, you build confidence through evidence. Instead of firefighting, you prevent problems before they happen.
The teams that adopt this approach in 2026 are the ones that will ship reliable AI products at scale. The ones that skip it will keep waking up to Slack messages about broken prompts.
Start small. Start today. Your future self will thank you when the next model update does not break your application.
For a deeper look at the specific metrics you should track, read 5 prompt engineering metrics that actually predict AI output quality. And if you want to see how version control fits into the bigger picture, check out why your AI workflows stall without a prompt versioning system.
Your Framework Is a Living System
A prompt testing framework is not a one-time project. It grows with your application. As you add new features, you add new test cases. As you encounter new failure modes, you update your evaluation criteria. As your team grows, the framework becomes the shared language for prompt quality.
Treat it like a garden. Plant the seeds. Water it daily. Pull the weeds before they take over. Do that, and you will see errors drop, confidence rise, and your product get better every week.
Now go write those test cases.