You have been shipping prompts to production for months. You know the feeling. You tweak one sentence in a system prompt, and suddenly your chatbot starts speaking in rhymes. Or your classification model returns a confidence score of 0.5 for every category. Without a structured way to measure these changes, you are flying blind. A prompt evaluation harness changes that. It gives you a repeatable, automated system to test prompts against a set of known inputs, score the outputs, and catch regressions before they reach users. This is not a theoretical exercise. It is a practical tool that every serious AI team should build.
A prompt evaluation harness is your safety net for LLM development. It automates the process of running prompts against a golden test suite, scoring the results, and detecting regressions. This guide walks you through the core architecture, scoring strategies, and CI/CD integration you need to build one in Python. You will learn how to design test cases, choose scoring methods, and set up a loop that catches prompt drift before it hits production.
What a Prompt Evaluation Harness Actually Does
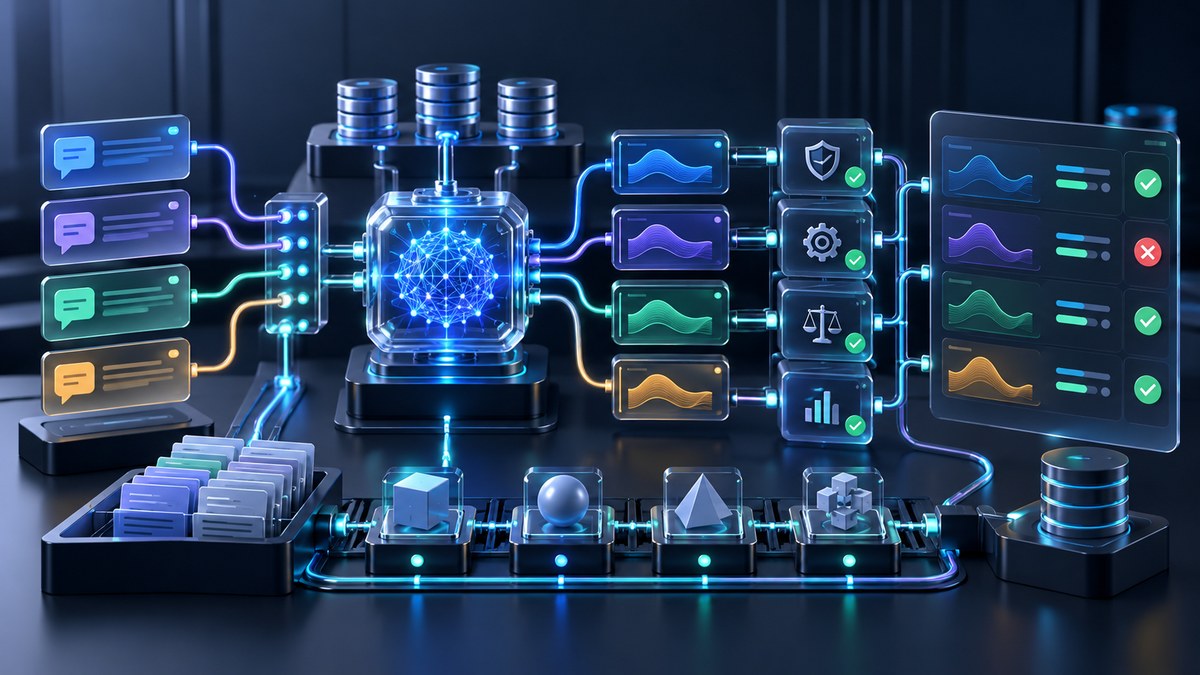
Think of it as a unit test suite for your prompts. You define a set of input-output pairs that represent desired behavior. The harness runs each prompt variant against those pairs, collects the model responses, and scores them against your criteria. If a new prompt version produces worse scores, you know before you deploy.
The core components are simple:
- A test runner that sends prompts to your model endpoint
- A scoring module that evaluates each response
- A results reporter that surfaces pass/fail and score trends
- A version tracker that links prompt changes to score changes
You can build this with standard Python libraries and a bit of async magic. The complexity comes from designing good test cases and picking the right scoring methods.
Designing Your Golden Test Suite
Your test suite is the heart of the harness. It should represent the full range of inputs your system handles in production. Start with these categories:
- Happy path inputs: The most common requests your users make
- Edge cases: Empty strings, very long inputs, unusual formatting
- Adversarial inputs: Prompts designed to trick the model into bad behavior
- Regression catches: Inputs that previously caused failures
For each test case, you need a reference output or a set of acceptable criteria. This does not have to be a single correct answer. For generative tasks, you can define rubrics instead of exact matches.
Here is a practical process to build your suite:
- Collect 100 to 200 real user queries from your production logs.
- Manually label each one with the ideal response characteristics.
- Identify patterns where the model currently fails.
- Write automated checks for those patterns.
- Version control the entire suite alongside your prompt files.
A good rule of thumb is to start with 50 test cases and grow to 200 as your system matures. You can always add more later.
Scoring Strategies That Actually Work
Scoring LLM outputs is the hardest part of building a harness. Exact string matching rarely works for generative tasks. You need methods that capture semantic correctness.
Here are the most reliable scoring approaches:
| Method | Best For | Weakness |
|---|---|---|
| Exact match | Classification, structured output | Fails on paraphrasing |
| Semantic similarity (embedding cosine) | Open-ended generation | Requires an embedding model |
| LLM-as-judge | Complex reasoning, tone, safety | Expensive, can be biased |
| Rule-based regex | Format validation, constraint checks | Brittle, misses nuance |
| Unit test for code generation | Code output | Only works for code tasks |
For most teams, a combination works best. Use exact match for structured fields, semantic similarity for content quality, and LLM-as-judge for safety and tone checks.
# Example: simple scoring pipeline
def score_response(response, expected, method="exact"):
    if method == "exact":
        return 1.0 if response.strip() == expected.strip() else 0.0
    elif method == "similarity":
        emb1 = embedding_model.encode(response)
        emb2 = embedding_model.encode(expected)
        return cosine_similarity(emb1, emb2)
    elif method == "llm_judge":
        return judge_llm.rate(response, criteria=expected)
    else:
        raise ValueError(f"Unknown method: {method}")
Building the Runner Loop
The runner loop is the engine of your harness. It takes a prompt template, a list of test cases, and a model endpoint, then returns scores. Here is the structure you need:
- Load the prompt template from a file or string.
- For each test case, render the template with the test input.
- Send the rendered prompt to the model endpoint.
- Receive the response and pass it to the scoring module.
- Collect all scores and compute aggregates.
You can run this synchronously for small suites, but for anything over 50 test cases, use async with a semaphore to control concurrency. Most model APIs have rate limits, so you need to respect those.
import asyncio
from semaphore import Semaphore

async def run_test_suite(prompt_template, test_cases, model_endpoint, concurrency=5):
    sem = Semaphore(concurrency)
    async def process_case(case):
        async with sem:
            rendered = prompt_template.replace("{{input}}", case["input"])
            response = await call_model(rendered, endpoint=model_endpoint)
            score = score_response(response, case["expected"], method=case["method"])
            return {"input": case["input"], "score": score, "response": response}
    tasks = [process_case(case) for case in test_cases]
    results = await asyncio.gather(*tasks)
    return results
Detecting Regression Before It Hurts
Regression detection is where the harness earns its keep. You run the same test suite against your current production prompt and your new candidate prompt. If the candidate scores lower on any critical test case, you block the deployment.
Set up a baseline score for each test case. This is the score your current prompt achieves. When you run a candidate, compare each score to its baseline. Flag any drop beyond a threshold you define.
For critical test cases, use a zero-tolerance policy. For less critical ones, allow a small margin. The key is to track trends over time, not just individual runs.
Expert advice: Never trust a single run. Run each test suite three times and take the median score. LLM outputs have natural variance, and a single bad sample can mislead you. Three runs give you a stable signal.
Integrating with CI/CD
Your harness is most valuable when it runs automatically. Integrate it into your CI/CD pipeline so that every prompt change triggers a full evaluation. Here is the workflow:
- Developer pushes a new prompt file to a feature branch.
- CI pipeline detects the change and runs the harness.
- Harness compares scores against the baseline from the main branch.
- If all scores pass, the prompt is approved for review.
- If any scores fail, the pipeline blocks the merge and reports which test cases regressed.
This loop turns prompt development into a disciplined engineering practice. You stop guessing and start measuring.
For a deeper look at how to structure your prompt testing workflows from prototyping to production, check out prompt testing workflows that scale. It covers CI integration patterns and reporting dashboards.
Common Mistakes and How to Avoid Them
Even experienced teams make these errors. Watch out for them:
- Testing with synthetic data only: Your test suite must include real user inputs. Synthetic data misses the weird edge cases that break models in production.
- Ignoring prompt ordering effects: The same prompt can produce different results depending on the order of few-shot examples. Randomize your examples during testing to catch this.
- Over-relying on LLM-as-judge: Using an LLM to score another LLM introduces bias and cost. Use it sparingly for subjective criteria only.
- Not versioning your test suite: Your test cases will evolve. Keep them in version control alongside your prompts so you can trace score changes to test changes.
- Running tests only once: As mentioned above, run each test multiple times and take the median. Variance is real.
Measuring What Matters
Not all metrics are created equal. Focus on the ones that predict real-world performance. Here are the metrics that actually matter:
- Pass rate: Percentage of test cases that meet your minimum score threshold
- Score stability: Standard deviation of scores across multiple runs
- Regression count: Number of test cases that scored lower than baseline
- Latency impact: How much the prompt change affects response time
Track these over time using a simple dashboard. When you see pass rate dropping or regression count rising, you know something is wrong before users complain.
For a broader view of the metrics that predict output quality, read about 5 prompt engineering metrics that actually predict AI output quality. It will help you decide which numbers to watch.
Building a Prompt Evaluation Harness That Grows With You
Your harness should not be a one-time project. Build it to evolve. Use a plugin architecture for scoring methods so you can add new ones without rewriting the runner. Store results in a database so you can query historical trends. Make the test suite easy to extend by using a simple JSON or YAML format.
Here is a checklist to get started:
- Define your first 50 test cases from production logs.
- Choose two scoring methods: one for structure and one for semantics.
- Write a basic async runner with rate limiting.
- Set up a baseline run and store the results.
- Write a comparison script that flags regressions.
- Integrate the comparison into your CI pipeline.
- Add a dashboard that shows pass rate over time.
Start small. Get the loop working. Then iterate.
The Real Value of Structured Evaluation
A prompt evaluation harness changes how your team thinks about prompt changes. Instead of “let’s try this and see what happens,” you move to “let’s measure this against our test suite and see if it improves.” It turns prompt engineering from an art into an engineering discipline.
The upfront cost is real. You will spend a few days building the harness and curating the test suite. But the payoff is continuous. Every future prompt change will be faster, safer, and more reliable. You will catch regressions that would have taken hours of manual testing to find. And you will sleep better knowing your production prompts are backed by data.
Start building your harness today. Your future self will thank you.