You have the model. You have the API key. But your AI outputs still feel like a coin flip. Sometimes they are brilliant. Other times they ramble, hallucinate, or completely miss the point. The difference between those two outcomes is rarely the model itself. It is how you talk to it. That is where prompt engineering patterns come in. These are not tricks. They are repeatable structures that force an LLM to think inside the lanes you define. For developers, data scientists, and technical product managers, mastering these patterns is the difference between a prototype that kind of works and a production system that delivers consistent business value.
Prompt engineering patterns are structured templates for interacting with LLMs. They reduce randomness and improve output quality for specific business tasks. This guide covers 10 patterns including chain-of-thought, few-shot, and role prompting. Each pattern includes a real business use case and a concrete example you can adapt today.
Why Patterns Beat Raw Instructions
Imagine telling a new hire “Write a report.” You will get a mess. Now imagine saying “Write a one page report summarizing Q3 revenue by region. Use bullet points for each region. Highlight any region that grew more than 10%.” That is a pattern. You gave structure, constraints, and a format.
LLMs work the same way. A raw instruction like “Summarize this text” leaves too much room for interpretation. A pattern gives the model a scaffold. It tells the model what role to play, what format to use, what examples to follow, and how to reason through the problem. When you apply these patterns to business applications, you get outputs that are accurate, consistent, and safe to use in front of customers.
The 10 Patterns That Solve Real Problems
Here are the patterns that work best in production. Each one solves a specific class of business problem.
- Chain-of-thought (CoT) prompting. Ask the model to explain its reasoning step by step before giving the final answer. This is the single most effective pattern for math, logic, and multi-step business analysis.
- Few-shot prompting. Provide two or three examples of the exact input-output pair you want. The model learns the pattern from the examples and applies it to new inputs.
- Role prompting. Assign a persona to the model. “You are a senior data analyst at a SaaS company.” This narrows the response style, vocabulary, and assumptions the model makes.
- Structured output prompting. Tell the model to return JSON, YAML, or a markdown table. This makes the output machine-readable and ready for downstream processing.
- Constraint-based prompting. Define boundaries. Word limits, forbidden phrases, required sections. This prevents the model from drifting into irrelevant territory.
- Contextual anchoring. Provide background context at the start of the prompt. This grounds the model in your specific business domain before you ask the question.
- Negative prompting. Tell the model what not to do. “Do not include pricing information.” “Do not mention competitors by name.” This is a safety net for customer-facing outputs.
- Persona constraints. Combine role prompting with a list of forbidden behaviors. “You are a customer support agent. You never blame the customer. You never speculate.”
- Iterative refinement. Use a multi-turn conversation where each prompt builds on the previous output. This works well for content generation and code review.
- Self-consistency sampling. Run the same prompt multiple times with a temperature setting above zero, then pick the most common answer. This reduces variance for high-stakes decisions.
A Practical Process for Applying Patterns
You cannot just read the list and hope it works. You need a repeatable process. Here is a five step workflow that works for any business task.
- Define the output. Write down exactly what you want the model to produce. A JSON object? A 200 word email? A decision tree? Be specific.
- Choose the primary pattern. If the task involves reasoning, start with chain-of-thought. If it involves format, start with structured output. If it involves tone, start with role prompting.
- Write the prompt template. Combine the pattern with a placeholder for dynamic data. For example: “You are a support agent. Here is the customer message: {message}. Write a reply that apologizes and offers a refund.”
- Test with three inputs. Run the prompt against at least three different inputs that represent real edge cases. Fix failures by adding constraints or examples.
- Version and monitor. Save the prompt in a versioned system. Track output quality over time. Models change. Your prompt may need adjustments.
Common Mistakes and How to Avoid Them
Even experienced engineers make these errors. Here is a table that shows the most common mistakes and the patterns that fix them.
| Mistake | What Happens | Pattern That Fixes It |
|---|---|---|
| Prompt is too vague | Output is generic and unhelpful | Constraint-based prompting |
| No examples provided | Model guesses the format incorrectly | Few-shot prompting |
| No role assigned | Output tone is inconsistent | Role prompting |
| Single turn used for complex tasks | Model misses intermediate steps | Chain-of-thought prompting |
| No output structure defined | Parsing fails in your pipeline | Structured output prompting |
| Context is missing | Model invents wrong assumptions | Contextual anchoring |
When to Use Each Pattern (A Decision Framework)
The hardest part is knowing which pattern to reach for. Here is a simple decision tree based on the business problem.
- Is the task analytical? Use chain-of-thought. This covers financial analysis, data extraction, and logic puzzles.
- Do you need a specific format? Use structured output. This covers API responses, database inserts, and report generation.
- Is tone critical? Use role prompting with persona constraints. This covers customer support, HR communications, and public facing content.
- Is the task repetitive with predictable variations? Use few-shot prompting. This covers email classification, intent detection, and data labeling.
- Is the output going to a customer? Use negative prompting plus role prompting. This prevents the model from saying something harmful.
- Is the task high stakes? Use self-consistency sampling. Run the prompt three times and take the majority answer.
A Real Example: Customer Support Ticket Classification
Let us walk through a concrete business problem. You need to classify incoming support tickets into three categories: billing, technical, and account management. You want the output as a JSON object with a confidence score.
Here is the prompt using three patterns combined.
You are a support ticket classifier for a SaaS company. Your job is to read the ticket and return a JSON object with two fields: "category" and "confidence".

The category must be one of: "billing", "technical", "account_management".

Examples:
Input: "I was charged twice this month. Can you refund the extra charge?"
Output: {"category": "billing", "confidence": 0.95}

Input: "I cannot log in. The page says 401 error."
Output: {"category": "technical", "confidence": 0.98}

Input: "I need to add a new admin to my team."
Output: {"category": "account_management", "confidence": 0.92}

Now classify this ticket:
Input: "My invoice shows the wrong company name."

Output:
This prompt uses role prompting (support ticket classifier), structured output (JSON), and few-shot prompting (three examples). It is production-ready. You can feed it into a pipeline and parse the JSON directly.
How to Build Your Own Pattern Library
You will get the most value when you stop treating prompts as one-off experiments. Instead, build a library of reusable templates. Each template should be a markdown file or a code string that contains.
- A description of the business problem it solves.
- The patterns used and why.
- The full prompt template with placeholders.
- Three test inputs and their expected outputs.
- A known failure mode and how to fix it.
A library like this saves hours each week. It also makes your AI workflows auditable. When a model update breaks a prompt, you can trace the issue back to the specific pattern and adjust it. If you want to see how to structure this at scale, check out this guide on how to build a prompt library that saves hours each week.
Measuring Pattern Effectiveness
You cannot improve what you do not measure. For each pattern you use in production, track these three metrics.
- Output accuracy. Does the output match the expected result? For classification tasks, this is a simple pass/fail. For generation tasks, use a human review or a second LLM as a judge.
- Latency. Chain-of-thought and self-consistency increase response time. If latency is critical, you may need to trade depth for speed.
- Token cost. Longer prompts cost more. Few-shot examples and contextual anchoring increase token usage. Measure the cost per task and optimize when you scale.
Expert advice: “The best pattern is the one you test. Do not assume a pattern works because it worked on a blog post. Run your own experiments. A pattern that fails 10% of the time is not a pattern. It is a bug.” – Senior ML engineer at a major e-commerce company.
Patterns for Advanced Workflows
Once you have the basics down, you can combine patterns into advanced workflows. Here are three that solve complex business problems.
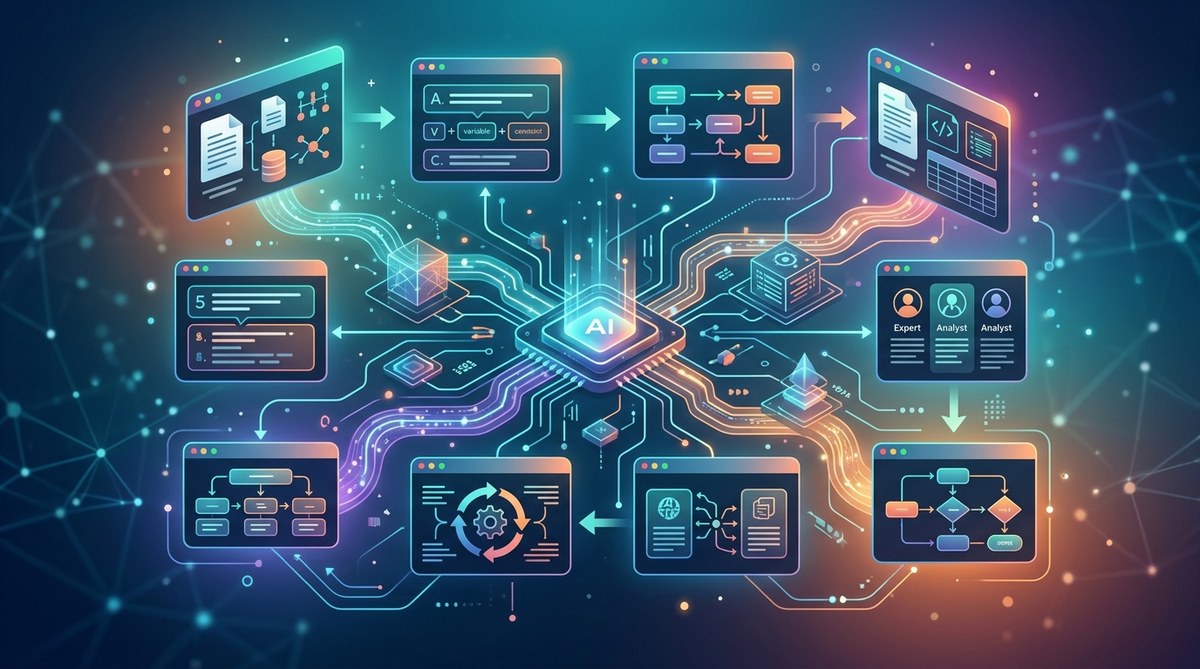
Prompt chaining. Break a large task into smaller steps. Each step uses a different pattern. For example, step one uses chain-of-thought to extract data from a document. Step two uses structured output to format that data into a database row. Step three uses role prompting to write a human readable summary. This approach is covered in detail in this article on using prompt chaining to get consistent output from AI writing tools.
Dynamic few-shot prompting. Instead of hardcoding examples, retrieve the most relevant examples from a vector database at runtime. This gives the model the best possible context for each input. It is especially useful when your data has many categories and you cannot provide examples for all of them. Read more about building smarter AI workflows with dynamic few-shot prompting.
Conditional prompts. Use if-then logic inside your prompt. For example: “If the customer mentions a refund, include the refund policy in your response. Otherwise, do not mention it.” This makes a single prompt handle multiple paths. For a deeper look at this technique, see how to craft conditional prompts for dynamic AI responses.
What to Do When Patterns Fail
Patterns are not magic. Sometimes they fail. When they do, here is a systematic way to debug.
- Check the model. Is it the right model for the task? A small model may not have the reasoning capacity for chain-of-thought.
- Check the examples. Are your few-shot examples consistent? If the examples contradict each other, the model will be confused.
- Check the constraints. Did you accidentally forbid the correct answer? Negative prompting can backfire if you are too aggressive.
- Check the context. Is the model missing critical information? Add contextual anchoring at the top of the prompt.
- Check the temperature. High temperature creates variance. If you need consistency, set temperature to 0.
If none of those fix the issue, the problem may not be the prompt. It may be the task itself. Some tasks are not suitable for LLMs. If the model consistently fails, consider a different approach like a fine-tuned model or a retrieval-augmented generation system. For a broader look at what is possible, the guide on top AI use cases transforming industries in 2026 can help you decide where to invest your effort.
Putting Patterns into Production
The jump from a working prompt in a notebook to a reliable prompt in production is larger than most people expect. Here are the key things you need.
- A prompt versioning system. Every change to a prompt should be tracked. When a model update breaks your output, you need to know what changed and when. This is covered in why your AI workflows stall without a prompt versioning system.
- A testing framework. Run a suite of test inputs against every prompt before you deploy. Automate this. The article on how to build a prompt testing framework that cuts errors by 80% walks through the exact implementation.
- A monitoring system. Track output quality in production. Use a second LLM call or a human review loop to catch failures early. The guide on 5 prompt engineering metrics that actually predict AI output quality gives you the numbers to watch.
The Shift Toward Automated Optimization
Manual prompt engineering is fading. In 2026, the best teams use automated tools to optimize their prompts. They run experiments where the system tweaks the wording, the examples, and the constraints, then measures which version performs best. This is not a replacement for understanding patterns. It is a force multiplier. You still need to know which pattern to start with. But the optimization can happen without you touching the keyboard. For more on this trend, read about the shift from manual prompt design to automated optimization in 2026.
One Pattern to Start With Today
If you only take one thing from this guide, start with chain-of-thought prompting. It is the highest leverage pattern for business applications. Every time you ask the model a question that involves reasoning, add the phrase “Think step by step” at the end of your prompt. Test it. You will see a measurable improvement in accuracy for analytical tasks. It works for data extraction, financial analysis, code generation, and decision support. It is free. It takes two seconds to add. And it solves the most common failure mode of LLMs: skipping the reasoning and jumping to a wrong conclusion.
Try it on your next prompt. You will see the difference.