Static few-shot prompting works great until your user asks something your examples didn’t cover. You load up a prompt with three perfect sample outputs, the model nails the first five queries, and then someone throws in a request from a completely different domain. The response drifts. The format breaks. You are back to tweaking examples by hand. Dynamic few-shot prompting solves this by selecting or generating the most relevant examples for each incoming request, so your LLM always sees context that actually matches the task.
Dynamic few-shot prompting replaces static example sets with a retrieval or generation step that picks the best examples for each user query. This technique reduces token waste, improves output consistency across diverse inputs, and scales better than manual prompt curation. AI engineers using this approach report fewer format errors and higher task accuracy without increasing model size or fine-tuning costs.
What Makes Few-Shot Prompting So Fragile
Standard few-shot prompting hands the model a fixed set of input-output pairs. The model learns the pattern from those examples and applies it to new queries. This works well when your users all ask similar questions. The problems start when your traffic includes multiple use cases, languages, or output formats.
Imagine you run a customer support triage system. Your static examples show how to classify billing issues, technical bugs, and account access problems. The model handles those three categories with high accuracy. Then a user submits a refund request that touches on both billing and policy. The model hesitates. It might pick the wrong category or produce a mixed format that your downstream parser cannot read.
Static few-shot prompting has three core weaknesses:
- Coverage gaps. You cannot include examples for every edge case without blowing past your token limit.
- Context dilution. Irrelevant examples confuse the model. Showing a model a complex code example when the current query is about simple text formatting hurts performance.
- Stale examples. As your product changes, your old examples become outdated. Updating them across every prompt is manual and error prone.
Dynamic few-shot prompting addresses all three by making the example selection part of the request pipeline.
How Dynamic Few-Shot Prompting Works
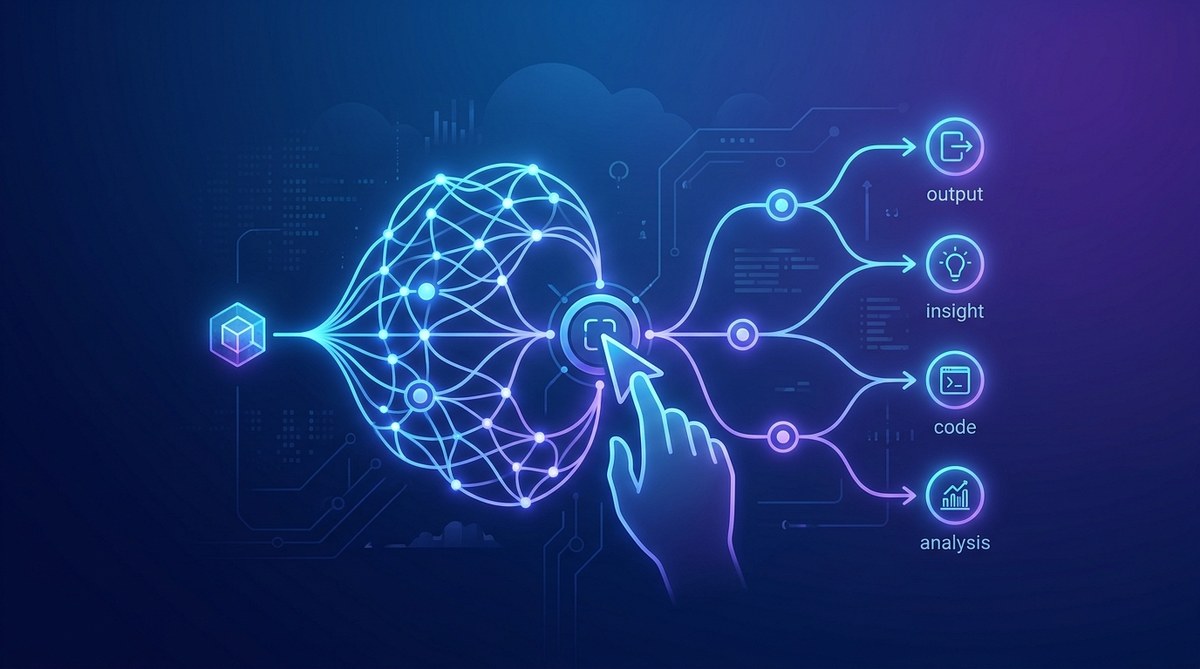
The core idea is simple. Instead of hardcoding examples into your system prompt, you retrieve or generate them at runtime based on the user’s input. The pipeline looks like this:
- Receive the user query.
- Embed the query into a vector representation.
- Search a database of example pairs for the most semantically similar matches.
- Select the top K examples (usually 2 to 5) that fit within your context budget.
- Inject those examples into the prompt template before sending it to the LLM.
This approach keeps your prompt lean and relevant for every single request.
A Concrete Example
Let us say you run a product description generator for an ecommerce platform. Your example database contains hundreds of pairs mapping product specs to marketing copy. A user sends in a query about a waterproof camping lantern.
Static prompting would show the model examples for electronics, outdoor gear, and kitchen appliances all at once. Dynamic prompting embeds the query “waterproof camping lantern,” finds the five closest examples from your database (all camping and outdoor lighting products), and only includes those. The model sees relevant context and produces a description that matches the category tone and format.
Building a Dynamic Example Retrieval System
You do not need a complex infrastructure to get started. Most teams already have the pieces in place.
Step 1: Curate Your Example Database
Start with 20 to 50 high quality input-output pairs per major task category. Each pair should represent a distinct variation in input style, output format, or domain. For a classification system, include examples from each class. For a generation system, include examples with different tones, lengths, and structures.
Store these pairs in a vector database like Pinecone, Weaviate, or pgvector. Generate embeddings using a model like text-embedding-3-small or a local alternative like all-MiniLM-L6-v2.
Step 2: Set Up the Retrieval Pipeline
When a new query arrives, generate its embedding and perform a similarity search. Return the top K results where K is determined by your token budget. A good starting point is 3 examples per query.
Consider adding a diversity filter. If all three retrieved examples look nearly identical, the model may overfit to that narrow pattern. A simple deduplication step based on embedding distance can prevent this.
Step 3: Format and Inject
Build a prompt template with a slot for the examples. The template might look like:
You are a customer support classifier. Below are examples of correctly classified tickets. Use them to classify the new ticket.

Examples:
{retrieved_examples}

New ticket: {user_query}
Classification:
The retrieved examples are formatted as pairs and inserted into the slot at runtime.
Common Mistakes and How to Avoid Them
Even a well designed dynamic few-shot system can fail if you overlook these details.
| Mistake | Why It Hurts | Fix |
|---|---|---|
| Using the same embedding model for retrieval and generation | Embedding models optimized for search may not align with the LLM’s internal representations | Test different embedding models against your LLM’s actual output quality |
| Retrieving too many examples | Wastes tokens and can confuse the model with conflicting patterns | Cap examples at 3 to 5. Measure performance as you add more |
| Ignoring example ordering | Models tend to favor examples placed later in the prompt | Randomize example order or place the most similar example last |
| Stale example database | Old examples teach outdated patterns | Set up a quarterly review cycle or log underperforming queries to identify missing examples |
| No fallback for empty retrieval | If no similar examples exist, the model gets no guidance | Define a default set of generic examples for queries with low similarity scores |
When to Use Dynamic vs. Static Few-Shot Prompting
Both approaches have their place. The table below helps you decide.
| Scenario | Recommended Approach | Reason |
|---|---|---|
| Single task with predictable inputs | Static few-shot | Simpler to maintain. No retrieval overhead. |
| Multiple tasks or domains | Dynamic few-shot | Each query gets relevant examples without manual switching. |
| Strict latency requirements under 200ms | Static or cached dynamic | Retrieval adds 50-150ms. Cache frequent queries. |
| Rapidly changing product or data | Dynamic few-shot | Update the example database without touching prompts. |
| Very long context windows (128k+ tokens) | Either works | Dynamic still reduces noise from irrelevant examples. |
Expert advice. Start with static few-shot for your core use case. Add dynamic retrieval only after you see degradation from coverage gaps. Premature optimization adds complexity without proportional gains. Measure first, then automate.
Measuring the Impact on Your Workflow
You need concrete metrics to justify the switch. Track these before and after implementing dynamic few-shot prompting:
- Format adherence rate. Does the output match your expected schema?
- Accuracy per category. Are certain domains improving more than others?
- Token consumption per request. Dynamic prompting should reduce token usage because you stop including irrelevant examples.
- Latency overhead. The retrieval step adds time. Measure p50 and p95 latency.
- Human correction rate. How often does a reviewer need to edit the output?
A typical improvement pattern shows a 15 to 30 percent reduction in format errors and a 10 to 20 percent decrease in token usage per request. The latency cost usually stays under 150 milliseconds with a well optimized vector store.
Practical Implementation Checklist
If you are ready to build a dynamic few-shot system, follow this numbered process.
- Audit your current prompts. Identify which ones use static examples and which tasks have the most input variety.
- Collect 50 to 100 example pairs for each high-variety task. Clean them for consistency.
- Choose a vector store. Start with pgvector if you already use PostgreSQL. It removes an infrastructure dependency.
- Write a retrieval function that takes a query string and returns the top K examples.
- Modify your prompt template to accept a dynamic example slot.
- Run an A/B test. Compare static vs. dynamic on the same traffic split for one week.
- Analyze the results. Look for improvements in accuracy, token usage, and error rates.
- Iterate on your example database. Add examples for queries that still fail.
For a deeper look at structuring your prompt templates, read our guide on how to use prompt templates to scale your AI workflows. If you are debugging why certain queries still fall through, the article on why your GPT prompts fail and how to fix them covers common pitfalls.
Making Dynamic Few-Shot Prompting a Habit
The teams that get the most out of this technique treat their example database like a living asset. They add new examples after every major feature release. They review retrieval logs to spot queries that returned poor matches. They treat the retrieval system as a component they tune, not something they set up once and forget.
Dynamic few-shot prompting turns your prompt engineering from a static document into an adaptive system. It does not require a larger model or expensive fine-tuning. It just requires you to be intentional about which examples your LLM sees and when.
Start small. Pick one prompt that handles multiple input types. Build your example database. Set up the retrieval pipeline. Run the comparison. Once you see the improvement in output quality and the reduction in manual corrections, you will wonder why you ever hardcoded examples in the first place.