Most writers blame the AI when a draft comes out wrong. The tool gets the side-eye. But the real culprit is almost always the prompt itself, specifically the kind that tries to do everything in one go. The inconsistency you keep seeing across runs is not a model problem. It is an architecture problem.
Prompt chaining is the most reliable path to repeatable, high-quality output from AI writing assistants.
- Single-shot prompts overload the model with too many competing instructions at once, producing output that varies unpredictably between runs
- Breaking prompts into sequential steps lets each stage focus on one clear task, reducing constraint interference
- Structured handoffs between steps preserve tone, audience definition, and editorial context through the entire draft
Why Single-Shot Prompts Produce Unpredictable Drafts
Imagine writing one prompt that asks an AI to produce a friendly but professional blog post targeting small business owners, avoiding jargon, using short paragraphs, including a call to action, staying under 800 words, and matching a specific brand voice. You have just asked the model to balance at least six separate constraints at the same time.
The model does not always weight those constraints the same way each run. Sometimes it prioritizes word count. Other times it goes heavy on the call to action and loses the tone entirely. Run that same prompt three times and you will likely get three drafts that feel like they came from three different writers.
This is not a flaw in the model. It is a flaw in the input. When every constraint arrives simultaneously, the model has no signal about which ones take priority. The variability is baked into the process from the first word of your prompt.
The pattern repeats across every AI writing tool on the market. The more constraints you pack into a single request, the wider the spread of outputs across runs. That spread is what makes single-shot prompting so frustrating for anyone trying to maintain consistent editorial standards at scale.
What Prompt Chaining Actually Means for Writers
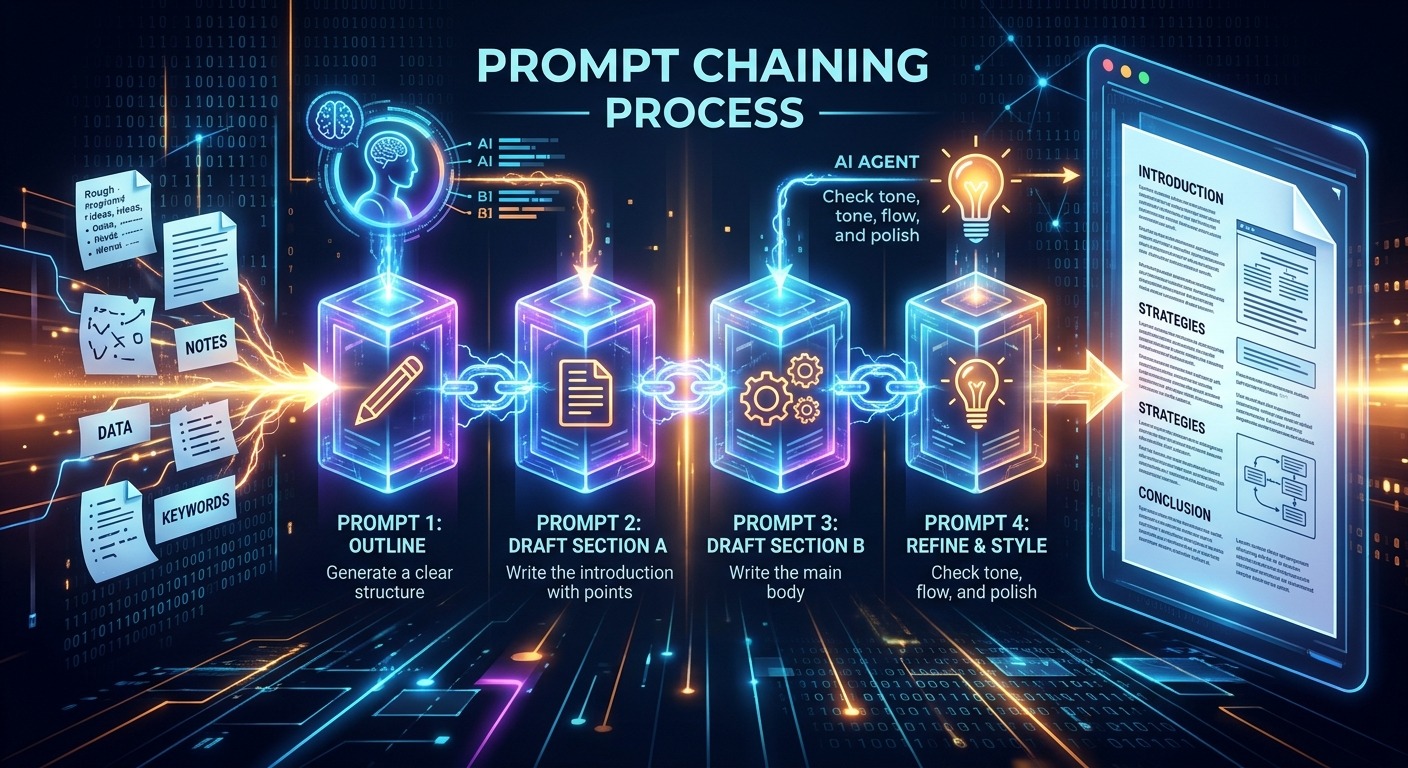
Prompt chaining means splitting a writing task into a sequence of smaller prompts where each one builds directly on the output of the previous step. Instead of one dense instruction block, you build a pipeline.
Think of it like a production line. Each station has one job. The output from station one becomes the input for station two. Nothing downstream starts until upstream is right. For a blog post, a basic chain might define the role and audience in the first step, generate an outline in the second, write each section from the approved outline in the third, and run a tone review in the fourth.
Each step is narrow. Each step is focused. And because the model is not trying to manage six things at once, the output is far more predictable across runs. Chain-of-thought research has shown that breaking tasks into explicit sequential steps measurably improves the reliability and quality of language model outputs. That finding holds just as strongly in writing workflows as it does in reasoning tasks.
The Three Layers That Drive Consistency
Role Assignment as the Foundation
Every chain should start by telling the model who it is. Not just “you are a helpful assistant” but something specific. You might say: “You are a senior content strategist writing for a fintech publication. Your readers are CFOs with 15 or more years of experience. Your job is to write with authority and without condescension.”
That framing shapes everything downstream. It is not decoration. It is the baseline from which all other instructions inherit their meaning. A model that knows its role will apply that role’s voice, vocabulary, and perspective without needing to be reminded at every step.
Constraint Layering Keeps the Model in Bounds
Constraints should arrive gradually, not all at once. After the role is established, the next step introduces style constraints: short sentences, active voice, no hedging language. These form layer two of the chain.
A third layer might handle structure: three main sections, one concrete example per section, a specific recommendation at the close. By separating these layers into distinct steps, each constraint gets full attention before the next one arrives. The adherence rate across multiple runs improves noticeably because the model is not forced to make tradeoffs between competing instructions.
Staged Handoffs Carry Context Forward
The handoff between chain steps is where most writers silently lose consistency. They take output from step one and paste it into a fresh conversation with no context. The model has no idea what came before and starts from a blank slate.
A good handoff explicitly carries the key decisions forward. Before step two begins, the prompt should include a concise summary of what step one established: the role, the audience, the tone markers. These become the anchor for every subsequent step. Drop the context and you drop the consistency. It is that direct a relationship.
How Tone and Audience Constraints Travel Through Real Chains
When you define a tone in step one, that tone needs to survive all the way to the final draft. The method that works reliably is treating tone as a named variable that every subsequent step references explicitly.
Step one might conclude by producing a “tone signature,” a single sentence describing the voice being used. Something like: “Authoritative but approachable; uses plain language; never talks down to the reader.” Step two opens by quoting that tone signature before generating the outline. Step three opens the same way before writing each section. The repetition is deliberate.
Carrying audience constraints works identically. The audience profile defined in step one should appear verbatim in every subsequent prompt, not paraphrased. Paraphrasing introduces drift, and drift compounds across every step until the final draft no longer reflects the original intent. Verbatim repetition feels redundant when you are writing the prompts. It does not feel redundant in the output.
You can see this working clearly in strut AI assistant, where structured prompt sequences carry tone and context consistently from one step to the next, producing drafts that stay on-voice even across long-form content. The difference between chained output and single-shot output becomes obvious when you compare multiple runs side by side. Chained outputs cluster tightly around the intended voice. Single-shot outputs scatter.
Building a Simple Writing Chain From Scratch
A practical five-step chain covers the full writing process without overloading any single prompt. The first step defines the role, audience, and tone, with the output being a role card and a one-sentence tone signature kept under 100 words. The second step generates an outline based on the role card and a brief topic description, returning a headline and three to five section titles with short descriptions of each.
The third step is a human review gate. You approve or revise the outline before any writing begins, because structural problems are far cheaper to fix at this stage than after a full draft exists. The fourth step writes each section using the role card, the approved outline, and the tone signature, all included verbatim in each section-level prompt. Not summarized. Not paraphrased. Verbatim.
The fifth step is a consistency pass. You ask the model to compare the final draft against the role card and tone signature, flagging sections that feel off-voice. Each step has one job. Each step has one output you can review before moving forward. The chain does not care how long the final article is because the hard decisions were already locked in before writing began.
Testing Your Chain: A Consistency Checklist
The whole point of chaining is repeatability. That means you need to measure it. Run the following checks against any writing chain before you treat it as production-ready.
- Run the chain three times on the same input without changing anything. Compare the outputs side by side. If the tone shifts noticeably between runs, the chain needs tighter tone constraints at the role-assignment step.
- Check whether the audience framing survived to the final draft. Ask someone who matches your target reader profile to read the output. Ask them directly: does this feel like it was written for you?
- Count constraint violations across all three runs. Pick five specific constraints from your chain, such as sentence length, word choice rules, and structural requirements. Count how many appear intact in the final output each time.
- Test your handoffs by removing the context summary from one step. If output quality drops noticeably, the handoffs are doing real work. If it barely changes, you may be carrying too little context between steps and relying on the model to fill gaps.
- Time the full production process. A chain that produces consistent output but takes four times as long as a single-shot prompt needs optimization. Look for adjacent steps that could be merged without losing constraint focus.
- Measure output spread over 10 or more runs. A well-designed chain produces outputs that are meaningfully similar in tone, structure, and quality across a large sample. A wide spread signals a weak link somewhere in the sequence that needs tightening.
Run these checks every time you build a new chain or significantly revise an existing one. The goal is not perfection on the first run. The goal is a measurable, documentable improvement in consistency across runs compared to a single-shot baseline.
From Scattered Drafts to a Writing System You Can Trust
Single-shot prompting treats AI writing like a lottery. Sometimes you get the output you need. Often you do not. And the most frustrating part is that you cannot easily diagnose why one run worked and another did not, because everything happened in the same opaque step.
Prompt chaining changes the frame entirely. Instead of hoping the model gets everything right at once, you build a system that makes each decision explicit, carries that decision forward, and gives you checkpoints where you can catch drift before it compounds into a flawed draft.
The consistency you have been looking for was never going to come from longer single prompts or better model versions alone. It was always going to come from better prompt architecture. A chain is not a workaround for a weak model. It is the actual methodology for any writing workflow that needs reliable results at scale.
Start with three steps: role, outline, draft. Measure the output spread across several runs. Tighten the handoffs where you see drift. Add constraint layers where the model wanders. The improvement is not cosmetic. It is structural, and it compounds the more you refine the chain.